 EntPEP
A new agent for every session.
Nothing carries over from one session to the next unless you choose to resume it, and nothing is reachable until you approve it.
Launch
Each session starts a fresh agent in its own sealed VM. Nothing is shared with other sessions or the host.
Approve
Switch on only what the work needs. Every capability starts off, and its choices appear only when you turn it on.
Enforce
The database decides which rows an agent sees, not the prompt. Grants are per table and time-boxed.
Record
Prompts, replies, queries and blocked attempts are written to your data lake, with signals flagged by severity.
Pick the sources. Launch.
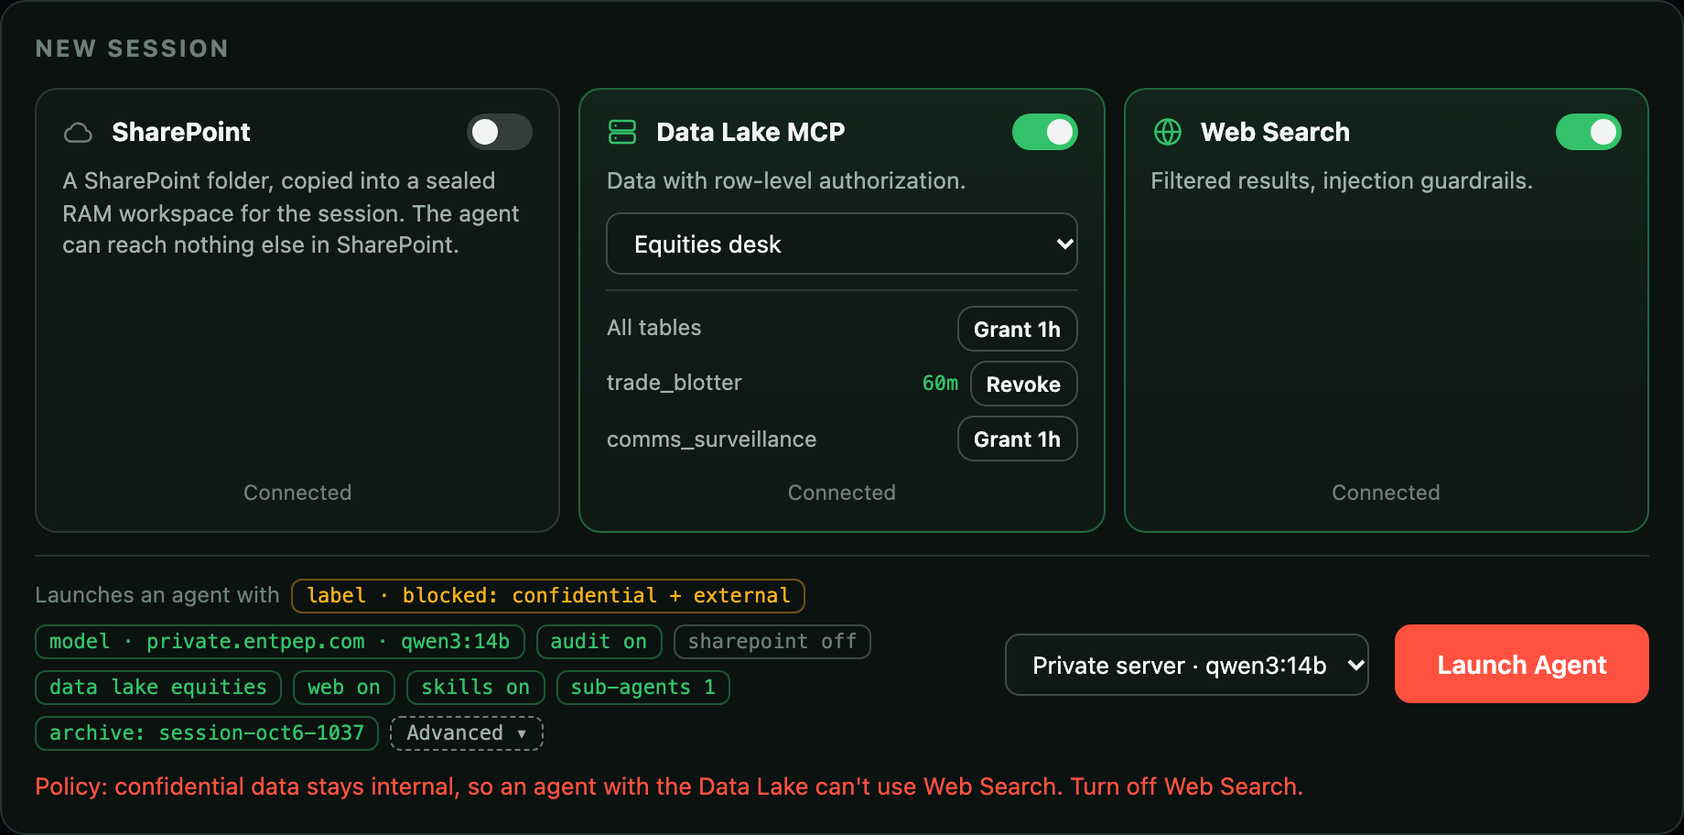
Most sessions need one to three sources, and each stays off until you approve it. Audit, skills, sub-agents and archive are on by default, one click away under Advanced. The launch line spells out exactly what the agent may reach before it exists.
One SharePoint folder, copied into RAM inside the agent. It is all of SharePoint the agent can reach, and it vanishes when the agent stops.
Data with row-level authorization: each desk sees only its own rows.
Policy-filtered results, with guardrails against prompt injection.
Prompts, replies and signals are written to the data lake.
Approved, pre-loaded skills your team publishes.
Hand a task to a background agent with the same permissions. Its result lands in the parent's workspace.
Session context and data can be saved and restored, or opened read-only.
More connectors, such as Splunk-style MCPs and other internal systems, are on the roadmap, each behind the same approval.
Choose the model server. Keep one set of rules.
Every model server runs under the same enforcement: a sealed VM per session, every prompt, model call, tool call and reply intercepted, credentials never shown to the model, and one audit trail.
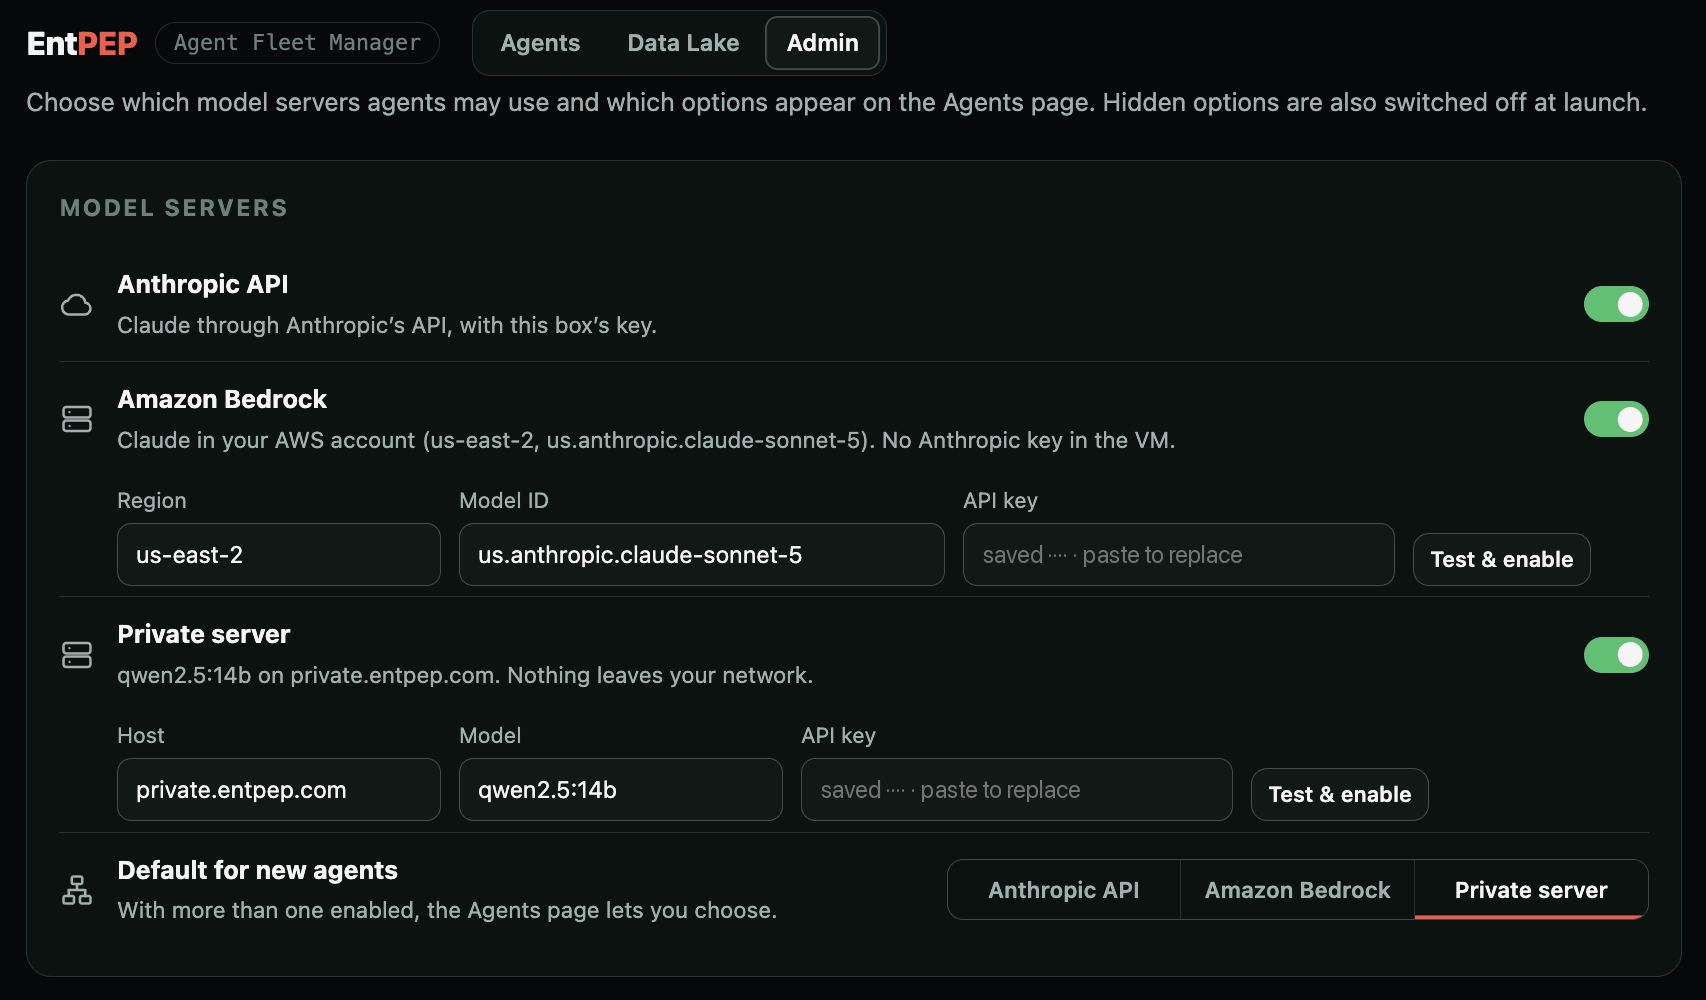
Anthropic, your AWS, or your premises
Admin enables one or more: the Anthropic API, Claude on Amazon Bedrock in your own AWS account (no Anthropic key in the VM), or a private server on your premises, where nothing leaves your network. With more than one enabled, the launch bar offers the choice and Admin sets the default. A sub-agent uses its parent's server.
No write-down
Every agent is labelled at launch: confidential if it can reach the Data Lake, external if it has Web Search or uses the Anthropic API. Bedrock in your account and your private server count as internal. Nothing moves from a confidential agent to an external one. With “Keep confidential data internal” on, one agent can't be both: the launch is refused and the refusal is audited.
Claude researches, the data stays put
The analyst stays confidential on an internal model. A person can hand public research to a sub-agent on Claude with Web Search only: no Data Lake, SharePoint or workspace. The typed task is checked against every value the Data Lake returned to the session and audited in full, and the results flow back to the analyst.
Governed by construction, not by instruction.
An agent on a laptop inherits everything the laptop can do. An EntPEP agent can only do what was compiled in and approved for this session.
Every action, intercepted before it takes effect.
EntPEP's patent-pending method intercepts each action an agent requests, evaluates it against centrally managed policy, enforces the decision before the action takes effect, and logs it to one record across users and agents. In Agent Fleet Manager it runs at five points inside every agent.
Your prompt
Before anything is sent.
Each model request
Context, memory and history included, before it leaves the agent.
Each tool call
Before it runs.
Each tool result
Before the model sees it.
Each reply
Before it reaches you.
Each hook can be switched on or off per agent, and every interception is written to your data lake. The same method governs Claude Code on the laptop and Claude.ai in the browser.
Real work on real data.
Teams that can't hand an agent the keys to everything, and still need it to read forty files and run the numbers.
Deal teams
Stage a data room into the agent's workspace, search it, and draft the summary. The files never land on a disk.
Desks and analysts
Ask questions of trade and loan data in plain English. Each desk sees only its own rows.
Compliance
Review flagged communications under a time-boxed grant, with every query on the record.
Claims pour in. Every decision follows the book.
A live claims queue, one click to take a claim, and an agent that checks it against the policy, the claims guidelines and past decisions before your adjuster or reviewer decides. Two walkthroughs: Property & Casualty (every new claim) and Life & Health (the claims that pend for a person). The model never sees who: names, emails, addresses and policy or member numbers reach it only as stand-ins.
Sample data for a fictional insurer, Brightwater Mutual, and its health plan, Brightwater Health. Agent answers are quoted from real runs on the claims shown.
Copilot finds. EntPEP proves.
Copilot answers from the passages most relevant to your question. That's fine for finding a document, and blind to what isn't there. Agent harnesses such as Claude Code make agents capable, but their rules and credentials live where the agent runs. EntPEP's agent gives every file a verdict, checks documents against your systems of record row by row, and compares wording with your house standard word for word, while the rules are enforced from the host, outside the agent. The appliance, not the model, keeps the ledger, and every step lands in your own data lake.
Every file
Completeness sweeps: a verdict for every file in scope, unreadable files listed with the reason, and no report may say “all” or “none” unless a finished sweep backs it.
Every row
Documents against the system of record: every confirmation matched to the trade blotter exactly, including the trades that have no confirmation at all.
Every word
Deviation from house standard: Legal's clause library against every agreement, approved fallbacks recognised, deviations saved as a Word redline.
Recorded live on the EntPEP Agent Fleet Manager; all demo data is simulated. Claude, Claude.ai and Claude Code are trademarks of Anthropic. Copilot is a trademark of Microsoft.
One agent per session. Approve what it can reach.
A short walk-through: pick sources and launch a sealed agent, choose where the model runs, see a confidential launch with Web Search refused, hand research to a Claude sub-agent, then watch the database return only one desk's rows, block an ungranted table, and log it all.
LLMs on your most confidential data, under your control.
A credit risk VP has to decide on a Barclays limit increase the same day. EntPEP lets her use large language models (LLMs) on data classified Confidential and Highly Confidential: it checks every agreement and confirmation, traces every figure to its source, and puts a signed record behind her decision. Simulated data; Barclays is only the example counterparty.
Already using Claude Code or Claude.ai? EntPEP also enforces policy on the endpoint and in the network, under one grant per user. Patent pending.
See the endpoint & proxy demo Sign inLaunch your first agent.
We'll set up Agent Fleet Manager on your server and connect your first resources.